The perimeter moved, and the data stayed valuable
For most of the last two decades, security budgets went into the walls. Firewalls, VPN concentrators, segmentation, an intrusion prevention box at the edge. That model assumed the data sat still inside a building you controlled. It does not sit still anymore. It lives in SaaS tenants, in three cloud providers, on laptops that travel, in managed databases that autoscale overnight, and increasingly inside the context windows of AI tools that staff paste sensitive records into without a second thought.
When the walls stop mapping to where the data actually is, the honest question changes. It stops being "is my network protected" and becomes "if a record left right now, would I know, and could I stop it." In a lot of the environments we assess, the answer to both halves is no. The logs exist somewhere, but nobody is watching the paths data takes out of the organisation, and the database that holds the customer table is trusted implicitly by every application server that can reach it.
This is not a niche concern. IDC's 2024 China data leakage prevention market-share report (Doc# CHC53572525) put that single national market at 932 million yuan, growing 3.7% year over year, and its companion report on database security auditing (Doc# CHC53571325) tracked a 1.24 billion yuan market growing 3.6%. Those are China figures, not global ones, but the direction of travel is the same everywhere we work: data-centric controls are a distinct, growing category, and buyers are moving spend from the perimeter toward the data itself. Both reports also flag the same pressure we see in the field, which is that AI is reshaping what these tools have to do.
What follows is how we approach data protection when a client asks us to actually reduce the chance of a leak, rather than pass a checkbox. Two controls carry most of the weight: data loss prevention at the endpoints and network egress points, and activity monitoring at the database. Neither works well bought in isolation, and both fail in predictable ways when the rollout skips the unglamorous first steps.
You cannot protect data you have not found
Every data protection project that stalls tends to have skipped the same step. Someone bought a DLP product, pointed it at the network, turned on the default policy pack, and then drowned in alerts that nobody could act on. The tool was never the problem. The problem was that the organisation could not answer a basic question: where does our sensitive data live, what kind is it, and who is supposed to touch it.
Discovery and classification come first, and they are tedious. You crawl file shares, object storage buckets, database schemas, email stores, and the SaaS apps that hold structured records. You tag what you find by sensitivity and by regulatory category, because a cardholder number, a passport scan, a salary record, and a signed contract carry different obligations. Cardholder data pulls in PCI-DSS. Personal data of UAE residents pulls in the Personal Data Protection Law, and DIFC or ADGM rules if you operate in those free zones. Health records pull in their own regime. Until each store is labelled, every downstream policy is a guess.
Classification is also where you decide how strict you can afford to be. Block every outbound file that looks like it contains a number in credit-card format and you will break the finance team's daily reconciliation within an hour. Get the classification right and you can write a policy that watches cardholder data specifically, from the systems that legitimately hold it, and leaves the rest alone. The quality of your classification sets the ceiling on how useful your DLP will ever be.
DLP is a data problem before it is a product
IDC defines DLP as the discovery, monitoring, and protection of sensitive information during storage and use, split across two enforcement points. Endpoint DLP sits on laptops, desktops, and servers, and enforces policy on the things a person does locally: copying a client list to a USB drive, dragging a file into a personal cloud sync folder, printing a batch of records. Network DLP inspects data in motion across email, web uploads, instant messaging, and file transfer, and blocks or quarantines sensitive content before it leaves.
Both matter because they cover different exits. Endpoint controls catch the offline paths that never touch your network gateway. Network controls catch the browser upload to a file-sharing site and the attachment on a personal webmail session. Run only one and you have a visible open door on the other side. The mistake we see most often is treating DLP as a single appliance decision rather than a set of coordinated policies enforced at every place data can leave.
There is a newer exit that neither classic mode was designed for, and it deserves its own attention. Staff now paste source code, customer records, and internal documents into public AI assistants to get work done faster. From a data protection standpoint, that is an outbound transfer to a third party, and most organisations have zero visibility into it. Modern DLP policy has to treat AI service endpoints as a monitored egress channel, the same way it treats webmail and cloud storage. IDC's DLP analysts make the same point from the vendor side, noting that protecting the data flowing into model training and inference has become a core direction for the category. The practical version for a defender is simpler: know which AI tools your people use, and put a policy in front of the sensitive data going into them.
The database is where the crown jewels actually sit
DLP watches the edges. It does not tell you what is happening inside the system that holds the largest concentration of sensitive data you own, which is almost always a database. This is the gap database activity monitoring fills, and it is the control most mid-sized organisations are missing entirely.
Database activity monitoring, or database auditing in IDC's phrasing, records and analyses the operations run against a database: who authenticated, what they queried, what they changed, and what they read. Done properly it gives you an independent record of access that does not depend on the application's own logs, which matters because a compromised application server or a stolen service credential will happily ask the database for the entire customer table, and the application log may show nothing unusual.
Two things make this harder than it sounds, and both are worth naming because they are why teams give up. First, production databases are noisy. A busy transactional system runs thousands of statements a second, with connection pooling that collapses many users behind a handful of service accounts, so "who did this" is not a column you can just read. Monitoring that ignores how the database actually handles concurrency and pooled connections produces logs you cannot attribute to a person. Second, the useful signal is a small fraction of the volume. A single application reading ten rows for a customer's account page is normal. The same credential reading ten million rows at three in the morning is the event you care about, and it will be buried unless you baseline normal behaviour first.
The standards assume you are doing this. PCI-DSS Requirement 10 is explicit about logging and monitoring access to cardholder data, and Requirement 7 about restricting access on a need-to-know basis. ISO 27001's Annex A controls for logging and privileged access point the same way. NIST's Cybersecurity Framework puts detection alongside protection as a first-class function. None of these are satisfied by an application that writes its own logs and trusts itself.
What each control sees, and where it is blind
It helps to lay the three controls side by side, because the value is in the coverage they give you together, not individually.
ControlWhat it watchesCatchesBlind spot
Endpoint DLP
Actions on laptops, desktops, servers
USB copies, local cloud-sync, printing, screen capture of sensitive files
Data accessed directly server-to-server; anything off the managed device
Network DLP
Data in motion: email, web uploads, messaging, file transfer
Exfiltration over the network, uploads to file-sharing and AI services, misdirected email
Encrypted channels it cannot inspect; offline paths; internal database reads
Database activity monitoring
Queries and changes against the database
Bulk reads, privilege abuse, unusual query patterns, changes outside change windows
What happens to the data after a legitimate application reads it
Read the blind-spot column top to bottom and the argument makes itself. Each control's gap is another control's job. A bulk read that database monitoring flags might then leave as a web upload that network DLP blocks. A file that endpoint DLP stops from reaching a USB stick might otherwise have been the copy an insider walked out with. The coverage is layered on purpose.
Why these projects stall
The technology is rarely the reason a data protection programme fails. The reasons are organisational, and they repeat across engagements.
The first is starting in blocking mode. A team turns on enforcement before it understands normal traffic, breaks a legitimate business process on day one, and loses the goodwill it needed to finish the rollout. The second is treating the whole thing as a compliance exercise. When the only goal is passing an audit, policies get written to satisfy a control matrix rather than to catch a real attacker, and the result is a tool that generates evidence but not protection. IDC's own analysts note that the market has moved past compliance as the sole driver, and that matches what buyers now expect: the programme has to reduce actual risk, not just produce a report.
The third is no owner. DLP and database monitoring both produce alerts that need a human to triage, tune, and act on. Stand up the tooling without assigning that function, usually inside a SOC or a managed detection service, and the alerts pile up unread until the console becomes wallpaper. The fourth is untuned noise, which is really a symptom of the first three. A programme that never invests in baselining and tuning will bury its analysts, and buried analysts miss the one alert that mattered.
A rollout that survives contact with production
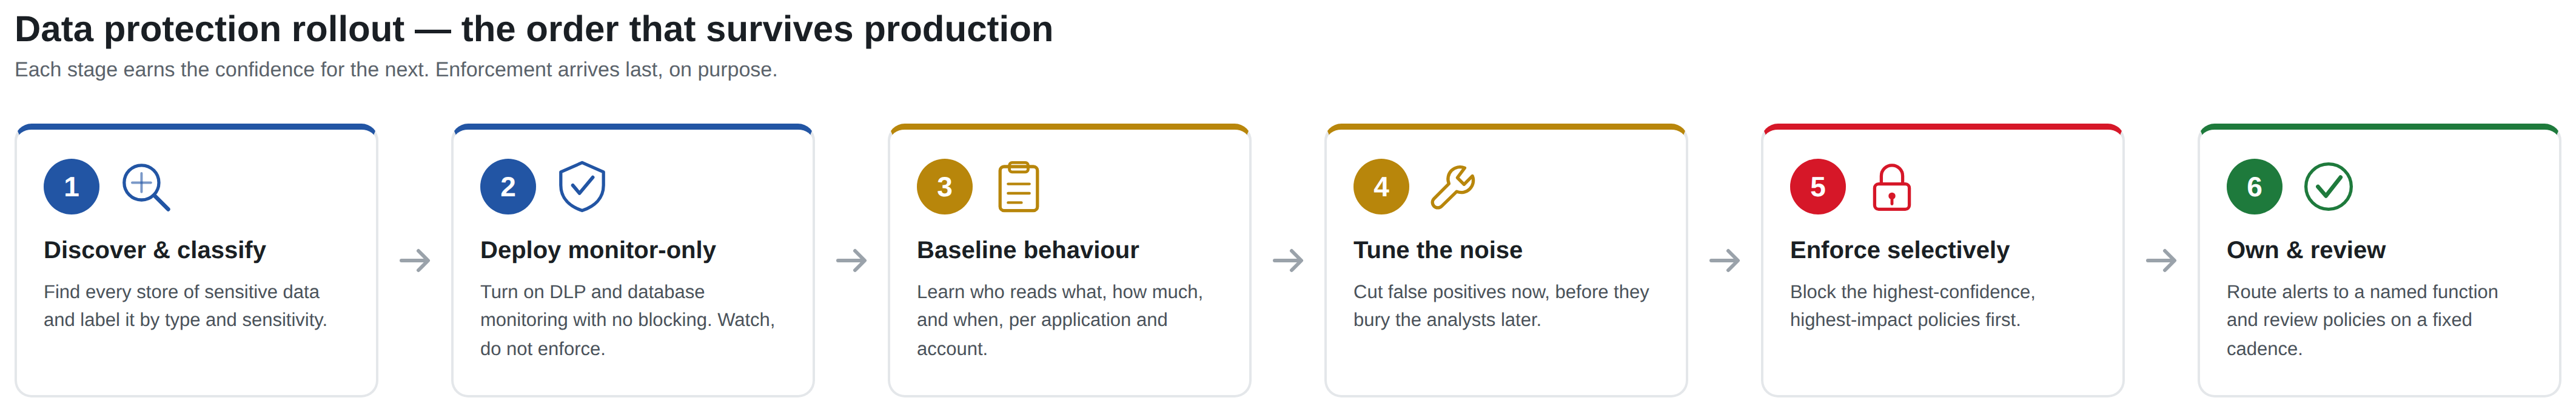
The sequence that works is not complicated, but the order is load-bearing. Skip a step and you inherit one of the failure modes above.
- Discover and classify. Find every store of sensitive data and label it by type and sensitivity. This is the foundation the rest of the programme stands on.
- Deploy in monitor-only mode. Turn on DLP and database monitoring with no blocking. Watch, do not enforce. You are learning what normal looks like.
- Baseline normal behaviour. Establish who reads what, how much, and when. For the database, this means understanding query patterns per application and per account, not per pooled connection.
- Tune before you enforce. Cut the false positives that would break legitimate work. Every noisy rule you fix now is an alert your analysts do not drown in later.
- Enforce selectively. Turn on blocking for the highest-confidence, highest-impact policies first: cardholder data leaving finance systems, bulk reads of the customer table, uploads of classified documents to unmanaged services.
- Assign ownership and review. Route alerts to a named function with the authority to act, and review the policies on a fixed cadence as the business and its data change.
Run it in that order and enforcement arrives late, on purpose, after you have earned the confidence that it will not break the business. That patience is the difference between a programme that ships and one that gets switched off after the first outage it causes.
 AI raises the stakes on both sides
Artificial intelligence changes this picture in two directions at once, and a serious programme accounts for both. On the risk side, generative AI has created a fast, casual path for sensitive data to leave the organisation, because pasting a document into an assistant feels like using a search box, not like transferring data to a third party. Enterprises are also feeding core data into model training and inference pipelines, which concentrates sensitive information in new places that classic controls never watched.
On the defensive side, the same technology is making the controls better. IDC's database-auditing report describes the shift from static rule execution toward systems that use large language models to parse intent, read variant SQL that a signature would miss, and build dynamic baselines of user behaviour. Applied to DLP, better semantic analysis means fewer false positives on classification, which is exactly the bottleneck that makes traditional deployments painful. We treat AI here as a force multiplier for the analyst, not a replacement for the sequence above. It sharpens detection and cuts noise, but it does not remove the need to discover your data, baseline your traffic, and own your alerts.
There is a third obligation that follows directly. If your organisation is building or adopting AI systems that touch sensitive data, the data pipeline feeding those models is now part of your attack surface. The training set, the vector store, the inference logs, and the prompts themselves can all leak regulated data. Extending data classification and monitoring to cover that pipeline is no longer optional for anyone deploying AI on real customer data.
Mapping the work to the standards you are measured against
For teams that have to show their work to an auditor or a regulator, the good news is that a well-run data protection programme satisfies several regimes at once. PCI-DSS covers the discovery and protection of cardholder data, the least-privilege access model, and the logging of access to it. ISO 27001's Annex A gives you the control language for classification, access control, and logging that most GCC enterprise and government buyers expect to see. NIST's Cybersecurity Framework organises the whole effort into identify, protect, detect, respond, and recover, which is a clean way to explain to a board why monitoring sits alongside prevention. For organisations handling personal data in the UAE, the Personal Data Protection Law and the DIFC and ADGM data protection regulations impose their own discovery, consent, and breach-notification duties that the same classification work underpins.
The point worth holding onto is that these frameworks are describing the same programme from different angles. You are not building a PCI project and an ISO project and a PDPL project. You are building one data protection capability and reporting it against each standard.
How Aydahwa Enterprise can help
We build and run data protection programmes for organisations across banking, telecom, and critical national infrastructure in the UAE and the wider GCC, and the sequence in this article is the one we use. Our work starts where most stalled projects should have: discovery and classification, so that every policy that follows is aimed at real, labelled data rather than a guess. From there we design and deploy endpoint and network DLP and database activity monitoring as a coordinated set of controls, tuned against your actual traffic before any enforcement is switched on, and integrated into your SOC or a managed detection service so the alerts reach someone who can act.
Our team holds the credentials that this work is measured against, including ISO 27001, PCI-DSS, SOC 2 alignment, NIST CSF, CIS Benchmarks, and Microsoft Cybersecurity Architect Expert certification, and we map every engagement to the standards and UAE regulations you report against. You can read more about our cybersecurity services and our cloud security and migration work, and if you run your own IT operations, our managed IT support covers the ongoing monitoring these controls depend on.
If you want to know where you stand before committing to a project, start with our free cybersecurity self-assessment and the cybersecurity readiness checklist. When you are ready to talk through a data protection programme for your environment, get in touch and we will scope it around the data you actually hold.