The moment an AI stops answering and starts acting
For most of the last two years, the AI that businesses actually ran in production was a chatbot. It sat behind a text box, answered questions, and did nothing on its own. The systems being pushed live now are a different animal, and the difference matters to anyone who signs off on risk. An AI agent reads a situation, decides what to do, calls a tool to do it, checks the result, and repeats until the job is finished. The instant a model can call an API, run code, query a database, or send mail without a human pressing the button on each step, it stops being a feature and becomes a privileged actor inside your environment.
That reframing is the whole security story. We have spent 25 years hardening the things that hold privilege: service accounts, integration users, scheduled jobs, the batch process nobody remembers granting domain admin to. An autonomous agent is another one of those, except it improvises. It decides at runtime which tool to call and with what arguments, and its decisions are shaped by text it reads along the way, some of which an attacker gets to write. In our engagements across banking, telecom, and critical national infrastructure, the pattern that worries us is not a rogue model. It is an ordinary agent, wired up quickly by a capable engineering team, that was given far more reach than the task ever needed.
The identity numbers make the point on their own. Machine and non-human identities already outnumber human users in most enterprises by a wide margin, and agents accelerate that curve because each one may hold several credentials to do its job. SailPoint's CISO put it plainly in a recent interview: identity has become the security frontline, and AI-driven identity defence now has to outpace the social engineering it is meant to stop. When the actor requesting access is a piece of software that negotiates its own next move, "who has access to what" is no longer a quarterly review. It is a live control problem.
An agent has five moving parts, and every one of them breaks differently
It helps to strip an agent down to its anatomy before arguing about how to defend it. Underneath the branding, an agent is close to a simple loop with five parts, and each part fails in its own way.
The model is the decision-maker, and it trusts what it reads
The language model is the brain. It interprets the goal, weighs options, and picks the next action. Its great weakness is also its purpose: it treats the text in its context window as instruction. It cannot reliably tell your system prompt apart from a paragraph it just fetched off a web page or pulled out of a support ticket. That is the root of prompt injection, and it is not a bug you patch. It is how the technology works.
Planning turns a fuzzy goal into concrete steps
Agents break hard tasks into smaller ones using techniques like chain-of-thought, tree-of-thought, or reflect-and-retry loops. The risk here is goal hijacking. If an attacker can nudge the plan, they do not need to defeat any single control. They redirect the whole sequence of actions toward an objective you never authorised, and the agent carries it out with your credentials.
Tools are where an agent touches the real world
A model with no tools is a brain in a jar. Tools are the functions it can call: web search, code execution, file access, database queries, internal APIs, increasingly exposed through the Model Context Protocol so any agent can discover and use them. This is the layer that turns a bad decision into a real incident. Over-broad tool permissions are the most common and most dangerous mistake we find. An agent given a database tool with write access "to be safe" now has a path to destroy data. A tool that fetches URLs becomes a server-side request forgery engine pointed at your internal network.
Memory is persistence, and persistence can be poisoned
Short-term memory is the context window. Long-term memory lives in vector stores, files, and knowledge bases the agent reads back later. Poison that store once, through a document the agent ingests or a prior conversation an attacker seeded, and the malicious instruction resurfaces on a future run against a different user. Memory also becomes an exfiltration route: sensitive data written into a shared store can leak across tenants if isolation is sloppy.
The loop is autonomy, and autonomy compounds
The four parts run in a cycle until the agent decides it is done. Left unbounded, that cycle is where cost overruns, runaway API calls, and slow data exfiltration over many small steps all live. The more autonomy you grant, the more the loop needs a leash.
Laid out this way, the defensive job gets clearer. You are not securing "AI." You are securing five components with five distinct failure modes, and most of them are problems your team already knows how to solve.
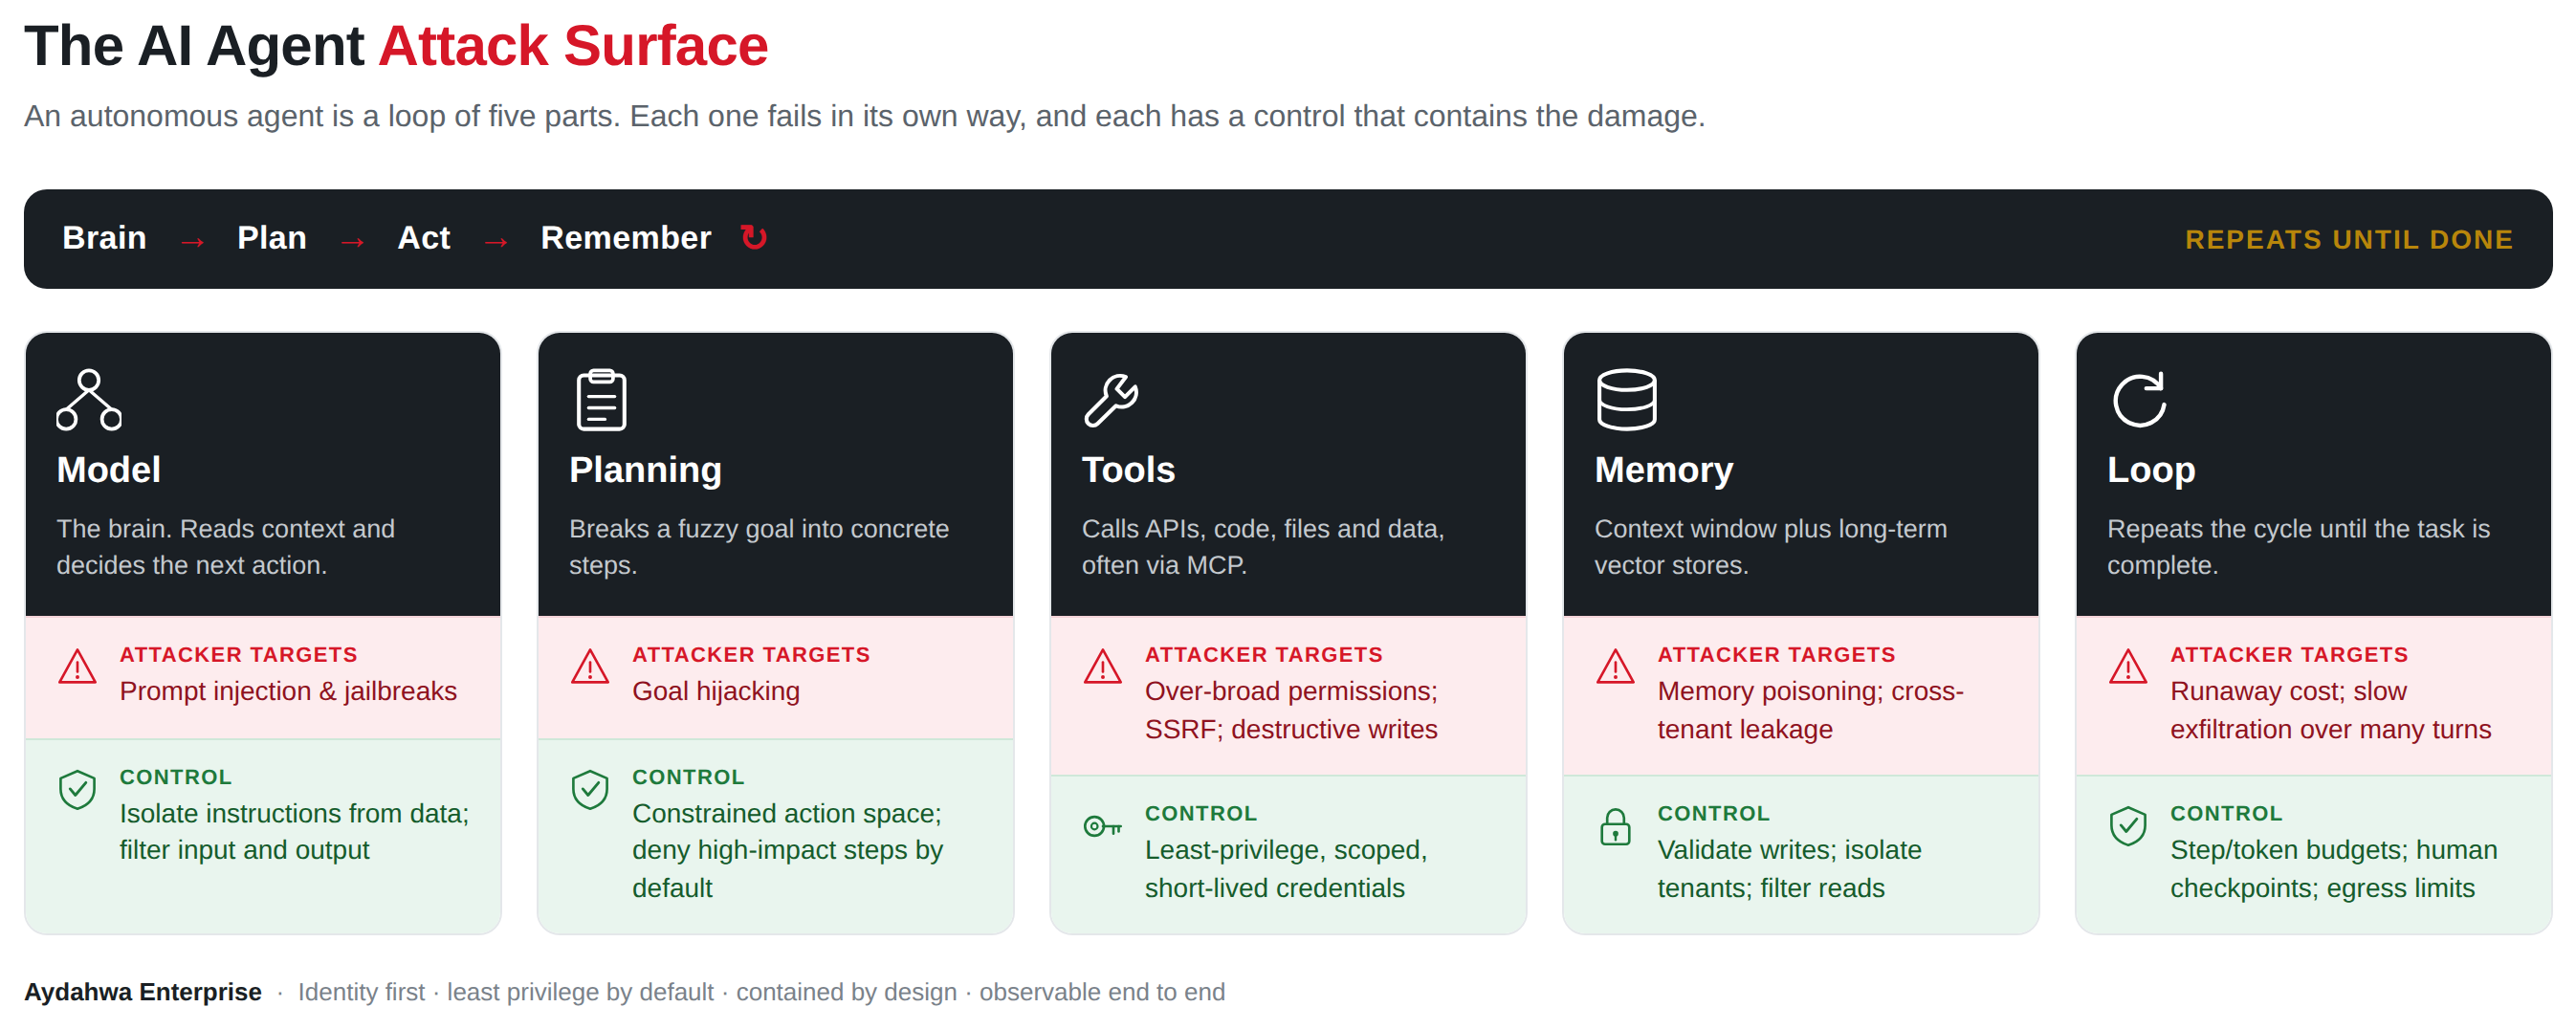
Where each part breaks, and what actually contains it
The table below is the working version of the model above. We use something close to it as a design checklist when we review an agent architecture, because it forces every component to have a named owner and a named control rather than a vague assurance that the model "has guardrails."
| Agent component | What an attacker targets | Control that contains it |
|---|---|---|
| Model (brain) | Prompt injection, jailbreaks, instruction override from fetched content | Separate trusted instructions from untrusted data, input and output filtering, treat all retrieved text as hostile |
| Planning | Goal hijacking, redirecting the action sequence | Constrained action space, plan validation, deny-by-default on high-impact steps |
| Tools | Over-broad permissions, tool poisoning, SSRF, destructive writes | Least-privilege scoped credentials per tool, allowlists, read-only by default, per-call authorisation |
| Memory | Memory poisoning, cross-tenant leakage, data exfiltration | Validate and sanitise what gets stored, tenant isolation, filter what retrieval returns |
| Loop | Runaway cost, rate abuse, slow exfiltration over many turns | Step and token budgets, rate limits, human checkpoints, outbound egress control |
Prompt injection is the injection flaw of this decade
If you internalise one threat from this article, make it this one. Prompt injection sits at the top of the OWASP Top 10 for LLM Applications as LLM01, and the comparison to SQL injection is apt. In both cases the system cannot cleanly separate trusted instructions from untrusted input, so a well-placed piece of data becomes a command.
The version that catches teams off guard is indirect prompt injection. Nobody types "ignore your instructions" into a chat box. Instead, the payload is planted in a document, a web page, an email, or a code comment that the agent reads as part of doing legitimate work. A support agent that summarises tickets can be told, by text buried in a ticket, to forward the customer database to an external address. A coding agent that reads a repository can be instructed, through a comment in a dependency, to leak secrets from the environment. The user asked for something ordinary. The agent obeyed a stranger.
There is no single filter that ends this. What works is a posture: assume every byte of retrieved content is potentially hostile, keep the agent's instructions out of the same trust zone as the data it processes, validate outputs before they trigger consequential actions, and never let a successful injection reach a tool that can do real damage on its own. That last point is the one that saves you. If injection succeeds but the tool it reaches is read-only and scoped to one tenant, you have an incident report instead of a breach. Vendors have started to build runtime monitoring specifically for this, such as Thales's AI Security Fabric watching LLM applications live for data leakage and jailbreak attempts, and that class of tooling is worth evaluating. It supplements the architecture; it does not replace it.
Identity is the perimeter now
The most durable control for agents is not an AI control at all. It is identity and access management applied with discipline. Every agent, and ideally every tool an agent can call, should run as its own identity with the narrowest set of permissions the task genuinely requires. Not the permissions that make development frictionless. The ones the job needs and nothing more.
This is where non-human identity governance earns its keep. Agent credentials should be short-lived, issued just in time, scoped to a single purpose, and revocable in seconds. When an agent needs to act on behalf of a specific user, it should carry that user's authorisation rather than a shared super-account that quietly accumulates the union of everyone's access. We have walked into environments where a single "automation" identity had rights across finance, HR, and production infrastructure because it was easier than provisioning three. An agent inheriting that identity is a breach waiting for a trigger. Get identity right and you cap the blast radius of every other failure on this page.
Guardrails that hold under pressure
Guardrails are not part of the anatomy, but they are what keeps autonomy from turning into expensive chaos. A few are non-negotiable in any production agent we would put our name on.
Sandboxing. Anything the agent executes, especially generated code, runs in an isolated environment with no standing access to production, no cloud metadata endpoint, and tightly controlled network egress. If the agent is compromised, the sandbox is the wall it hits.
Human-in-the-loop on consequential actions. Reading data can be autonomous. Moving money, deleting records, changing access, or sending external communication should pause for a human until the agent has earned trust on that action through a long track record. Draw the line by blast radius, not by convenience.
Output validation. Treat the model's output as untrusted input to the next system. Validate structure, check that requested actions fall inside policy, and strip anything that looks like an attempt to reach beyond scope before it is executed.
Budgets and egress control. Cap steps, tokens, and tool calls per task. Monitor and restrict where the agent can send data. Most exfiltration through an agent is not one dramatic dump. It is a steady trickle across a long loop that nobody was watching.
Observability built for agents. Log every decision, tool call, argument, and result, and feed that telemetry into the SOC and SIEM you already run. An agent's action log is your detection surface. Pair it with proactive exposure management, of the kind platforms like NordStellar now offer by scanning for leaked credentials and data before attackers use them, so a compromised agent credential surfaces before it is abused.
A pre-production gate for any agent
When a team brings us an agent to review before launch, we run it against a short, unforgiving list. Nothing here requires exotic tooling. It requires the discipline to say no until each item is answered.
- Does every tool the agent can call run with least-privilege, scoped, short-lived credentials, and is every high-impact tool read-only or gated behind a human check?
- Is all retrieved and ingested content treated as untrusted, with the agent's instructions held in a separate trust zone from the data it processes?
- Are consequential actions, meaning anything that moves money, changes access, deletes data, or communicates externally, paused for human approval?
- Does generated code and any tool execution run in a sandbox with controlled network egress and no standing production access?
- Are step, token, and rate budgets enforced, and is outbound data flow monitored and capped?
- Is long-term memory validated on write, isolated per tenant, and filtered on read to prevent poisoning and cross-tenant leakage?
- Is every decision, tool call, and result logged and streamed into your SOC or SIEM, with alerting on anomalous behaviour?
- Has the agent been red-teamed against prompt injection, including indirect injection through the exact content sources it will read in production?
An agent that passes all eight is not invulnerable. It is defensible, observable, and contained, which is the realistic goal. An agent that fails three of them is not ready, however impressive the demo looked.
This maps onto the frameworks you already report against
None of this asks you to throw out your compliance programme and start again. The controls above slot into standards you likely already work with. The OWASP Top 10 for LLM Applications gives you a shared vocabulary for the specific risks. MITRE ATLAS catalogues real-world adversary techniques against AI systems and is a useful basis for threat modelling and red-team scoping. The NIST AI Risk Management Framework provides the governance structure for identifying and managing these risks across the lifecycle, and ISO/IEC 42001 offers a certifiable AI management system that sits alongside the ISO 27001 you may already hold.
The value of anchoring to these is practical. When an auditor, a board, or a client in a regulated sector asks how you govern autonomous AI, you can point to a recognised framework and a mapped set of controls rather than a promise that the vendor handles it. For teams working toward ISO 27001, PCI-DSS, SOC 2, or NIST CSF alignment, treating agents as the privileged identities they are keeps them inside the access-control, logging, and change-management regimes those standards already demand.
How Aydahwa Enterprise can help
Aydahwa Enterprise designs and secures the infrastructure that autonomous systems run on. We come at AI agent security the way we come at any other privileged actor in an environment: identity first, least privilege by default, contained by design, and observable end to end. Our background spans enterprise infrastructure and cybersecurity across banking, telecom, and critical national infrastructure, and our control designs are built to map cleanly to ISO 27001, PCI-DSS, SOC 2, NIST CSF, and the CIS Benchmarks, backed by Microsoft Cybersecurity Architect Expert credentials on the team.
If you are putting AI agents into production, or already have and want an honest assessment of what they can reach, we can help with architecture review, identity and access design for non-human actors, sandboxing and egress control, and SOC and SIEM integration so agent activity is actually watched. Explore our cybersecurity services and cloud security and migration work, or lean on our managed IT support to keep these controls healthy over time. To gauge where you stand today, run our free cyber security self-assessment and work through the cybersecurity readiness checklist. When you are ready to talk specifics, get in touch, and we will start with the question that matters most: what can your agents actually reach, and who decided they should?